Image data
Photos captured or sourced to your scenarios, devices, lighting and demographics.
Custom data collection across text, image, audio and video, fueling high-performance AI models from the ground up.
Image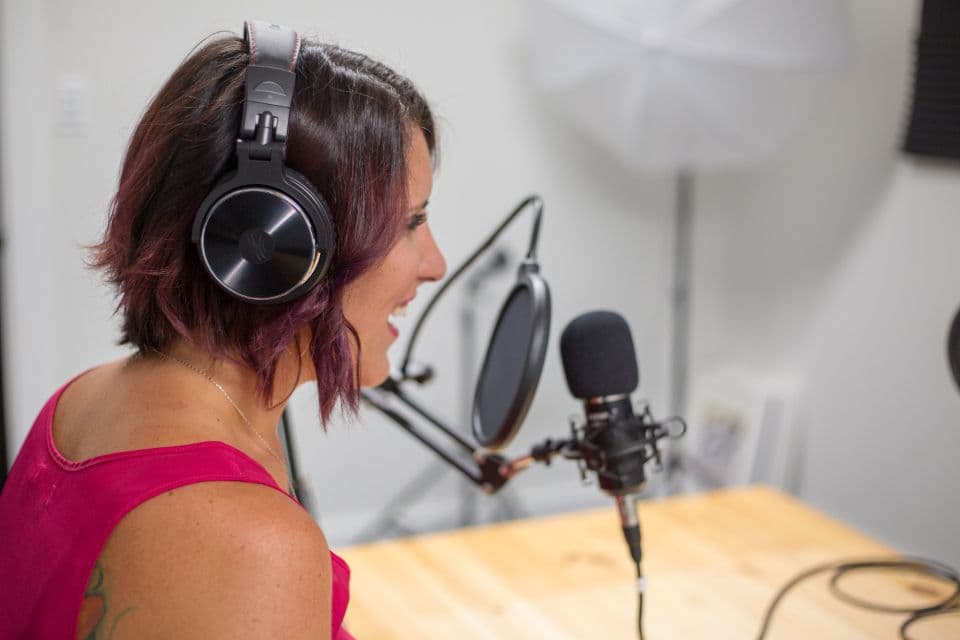 Speech
 Medical
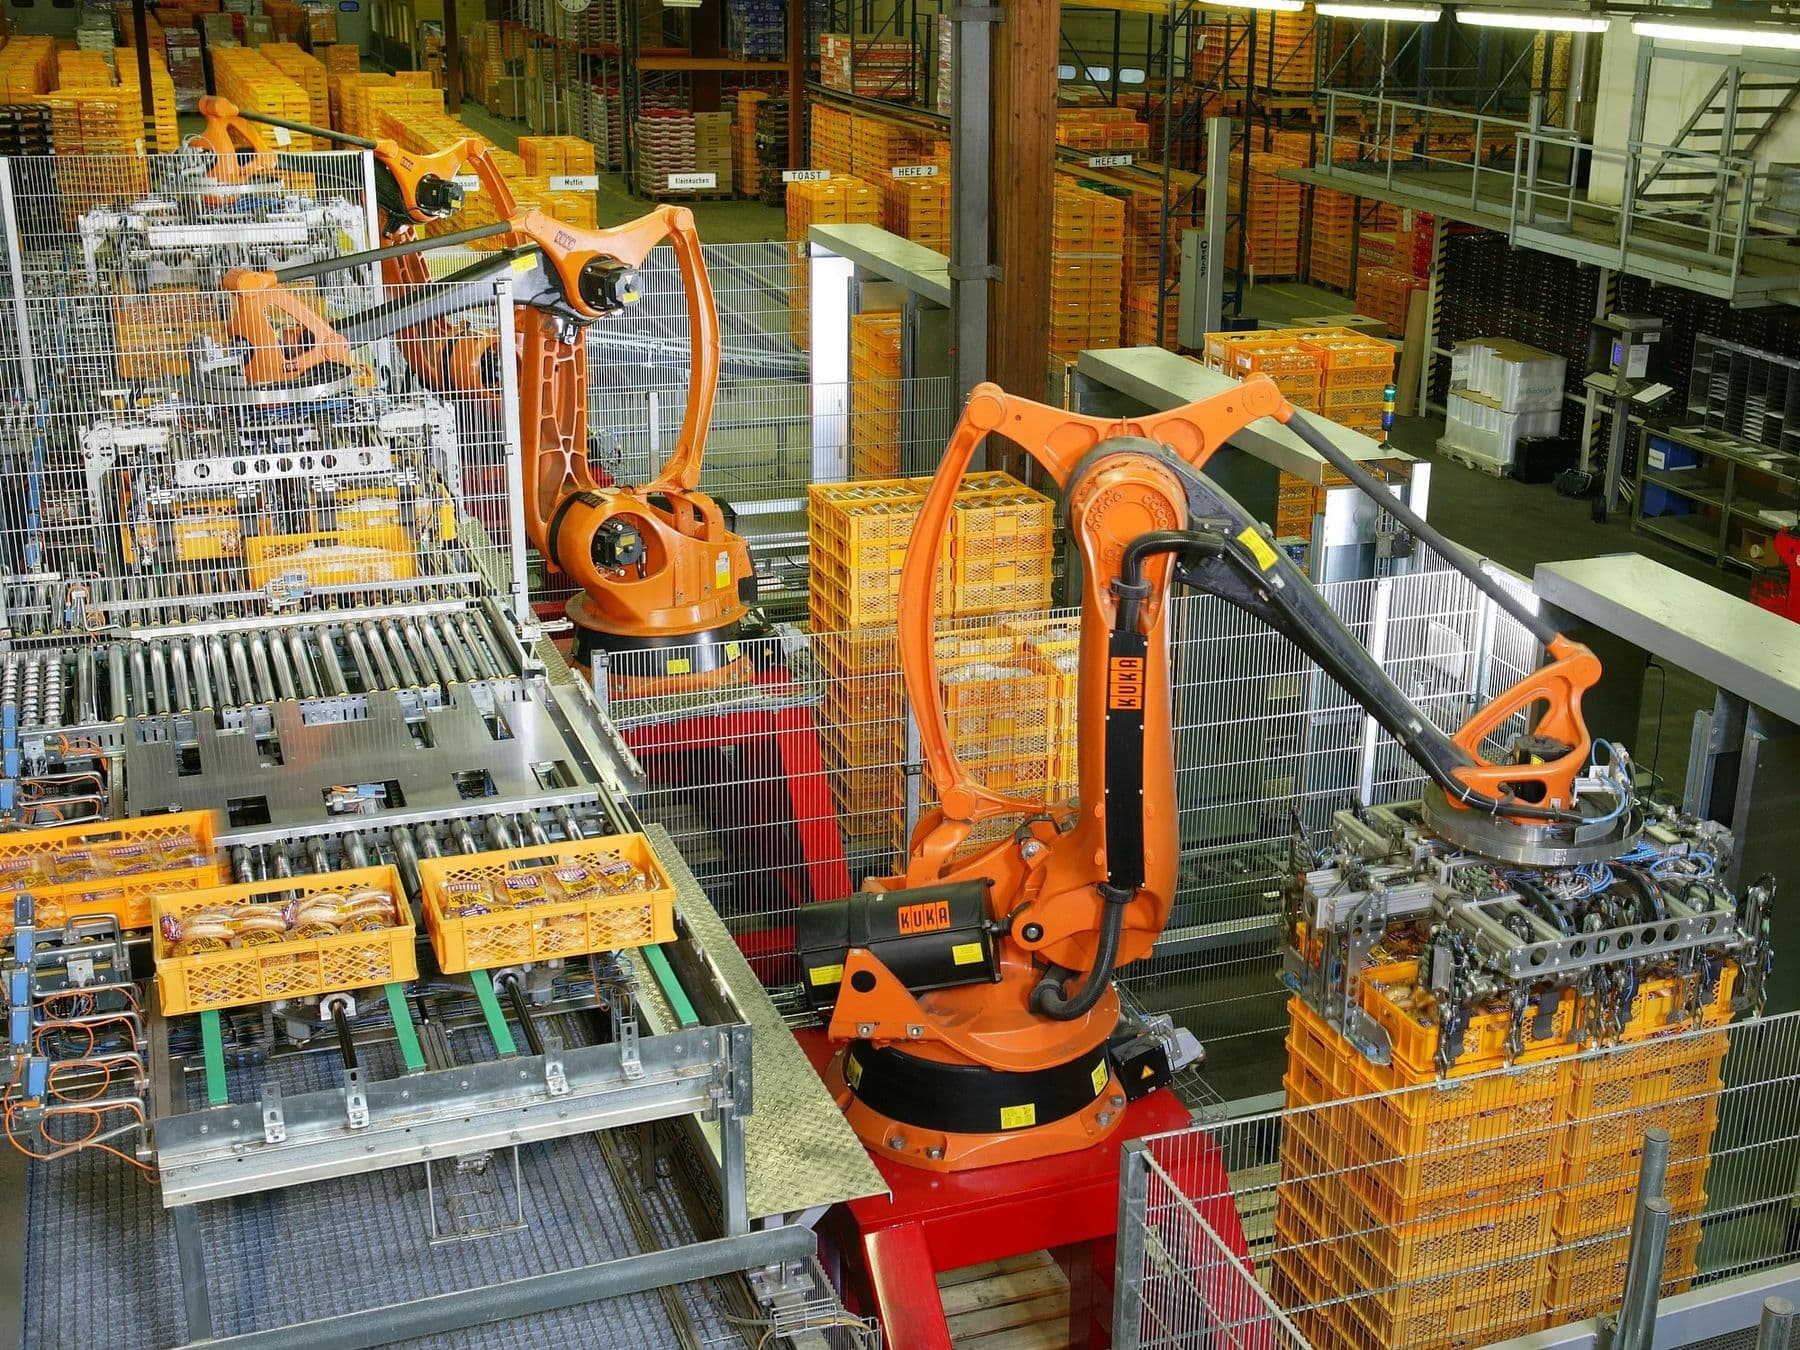 Manufacturing
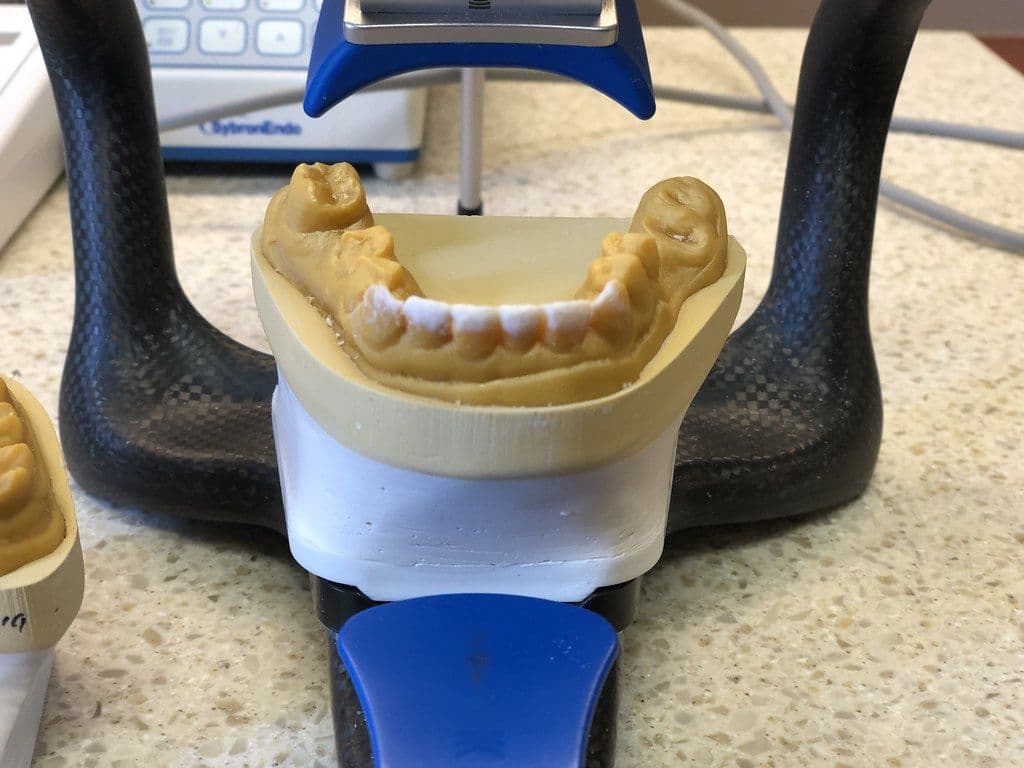 Dental
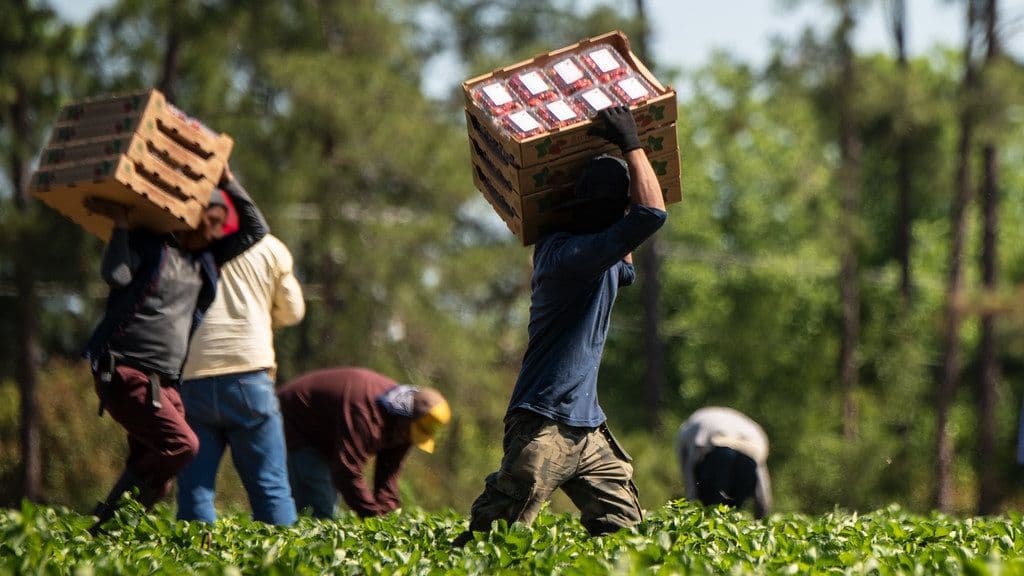 Agriculture
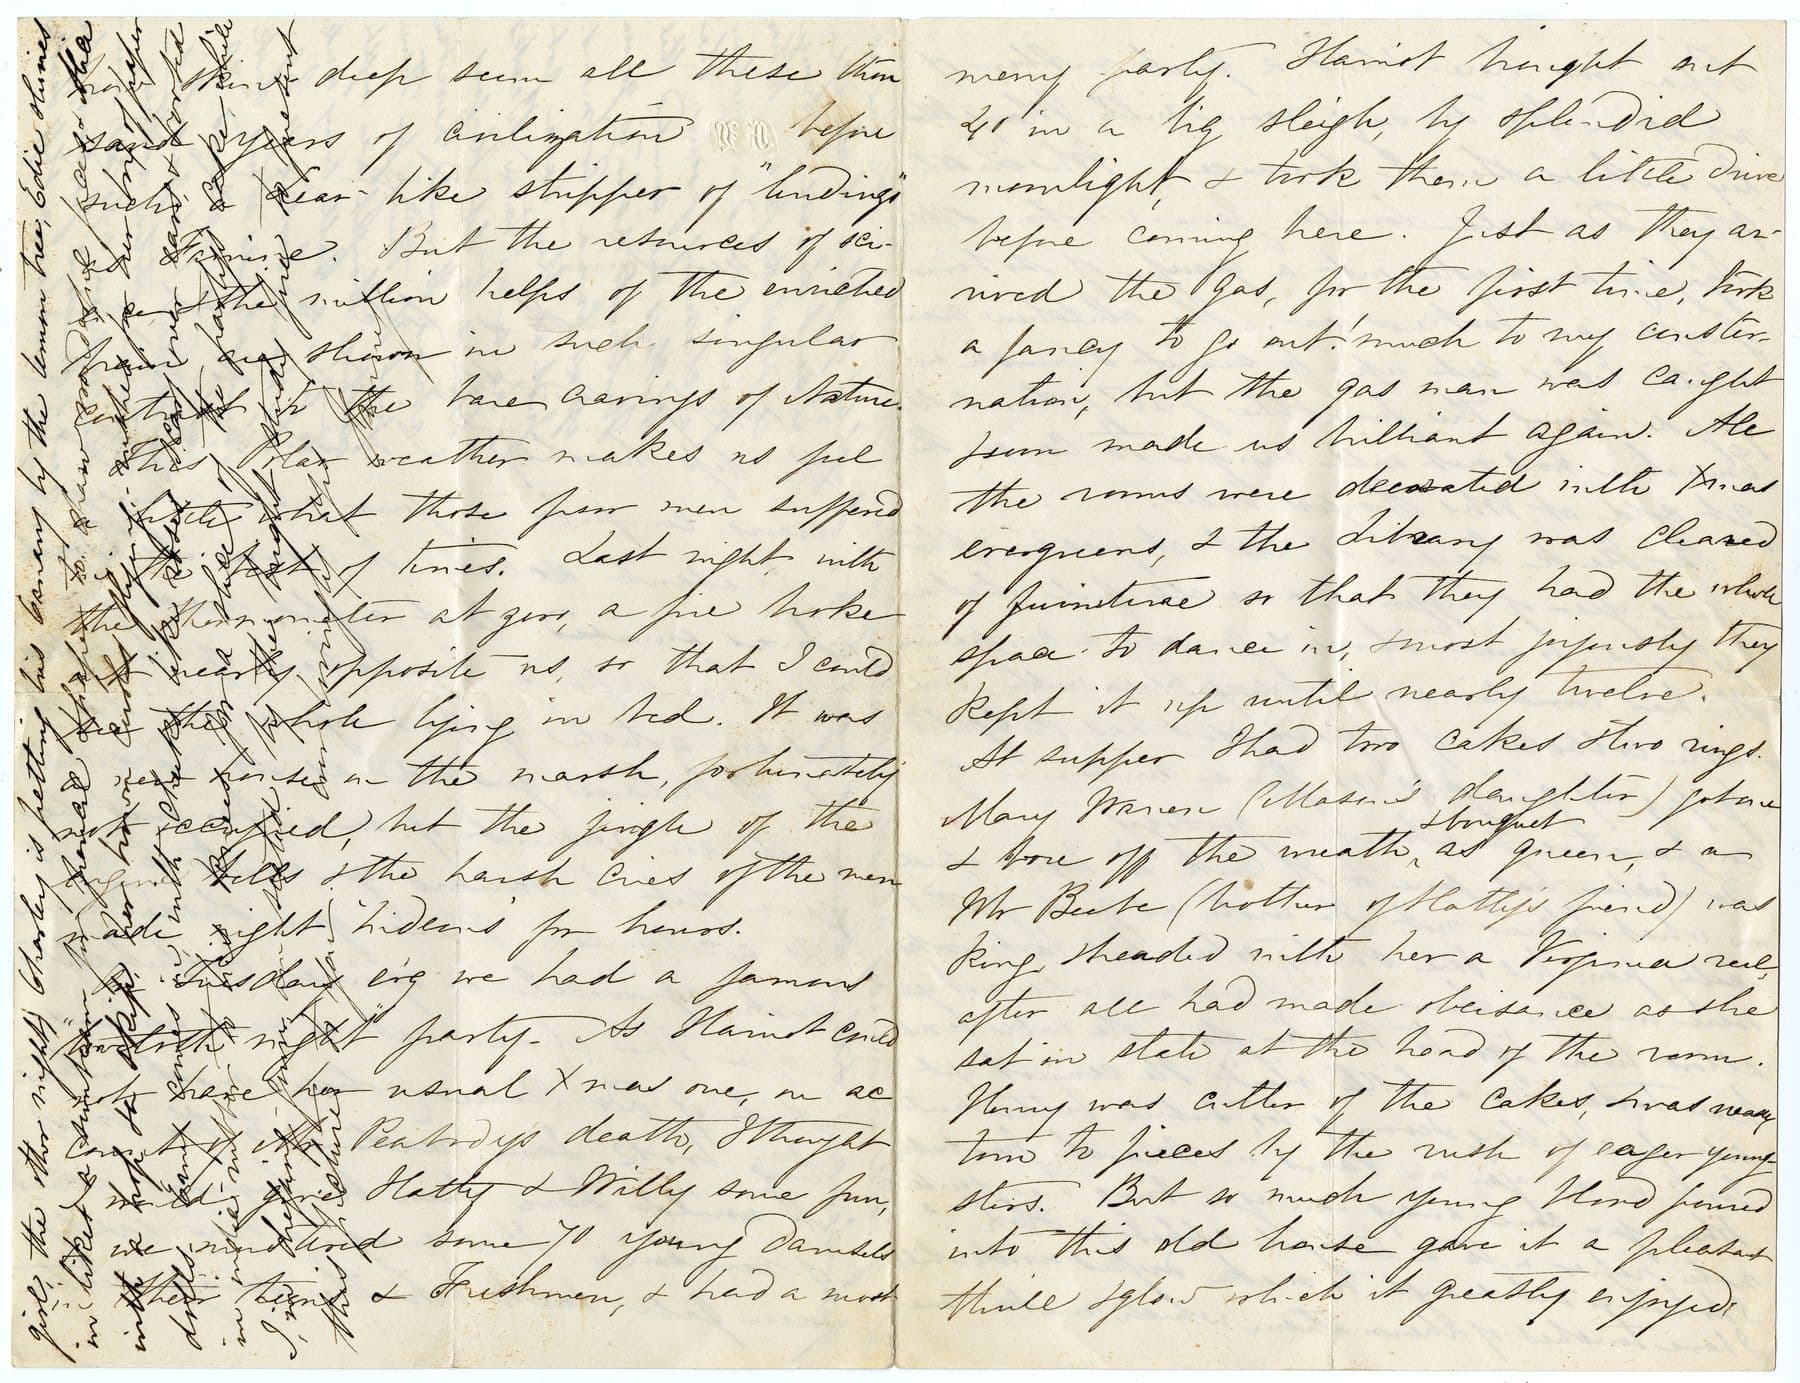 Documents
 Retail
What we collect
We source, generate and curate datasets tailored to your use case. From real-world images to multilingual speech and domain-specific text, you get accurate, diverse and ethically sourced data.
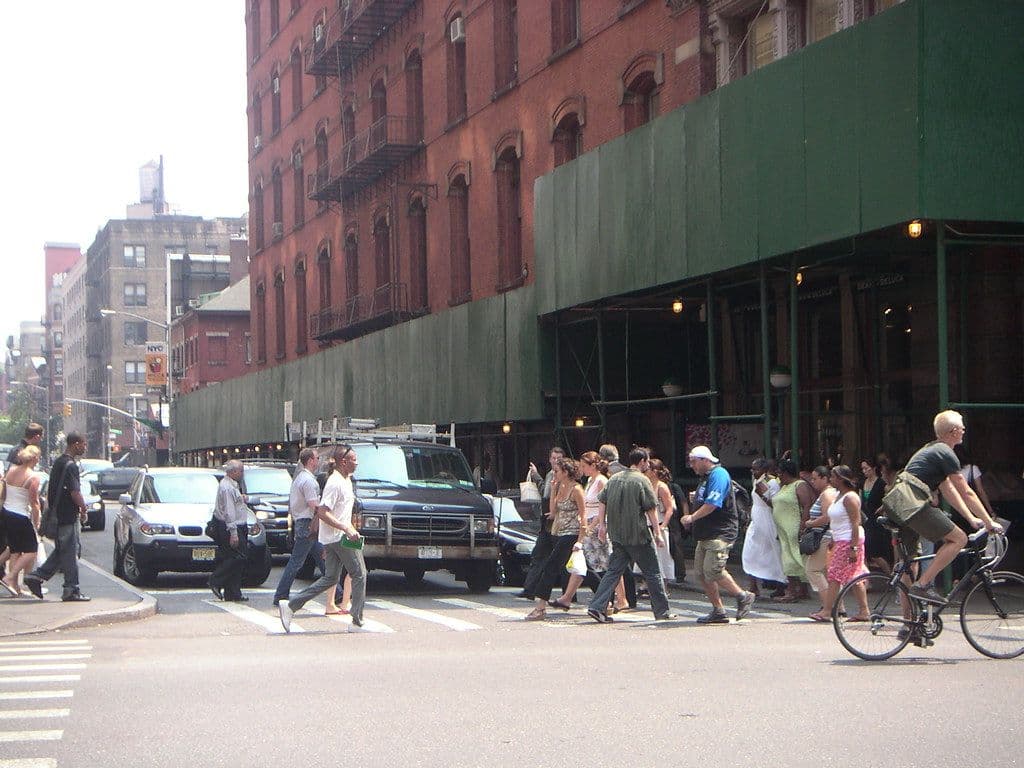
Photos captured or sourced to your scenarios, devices, lighting and demographics.
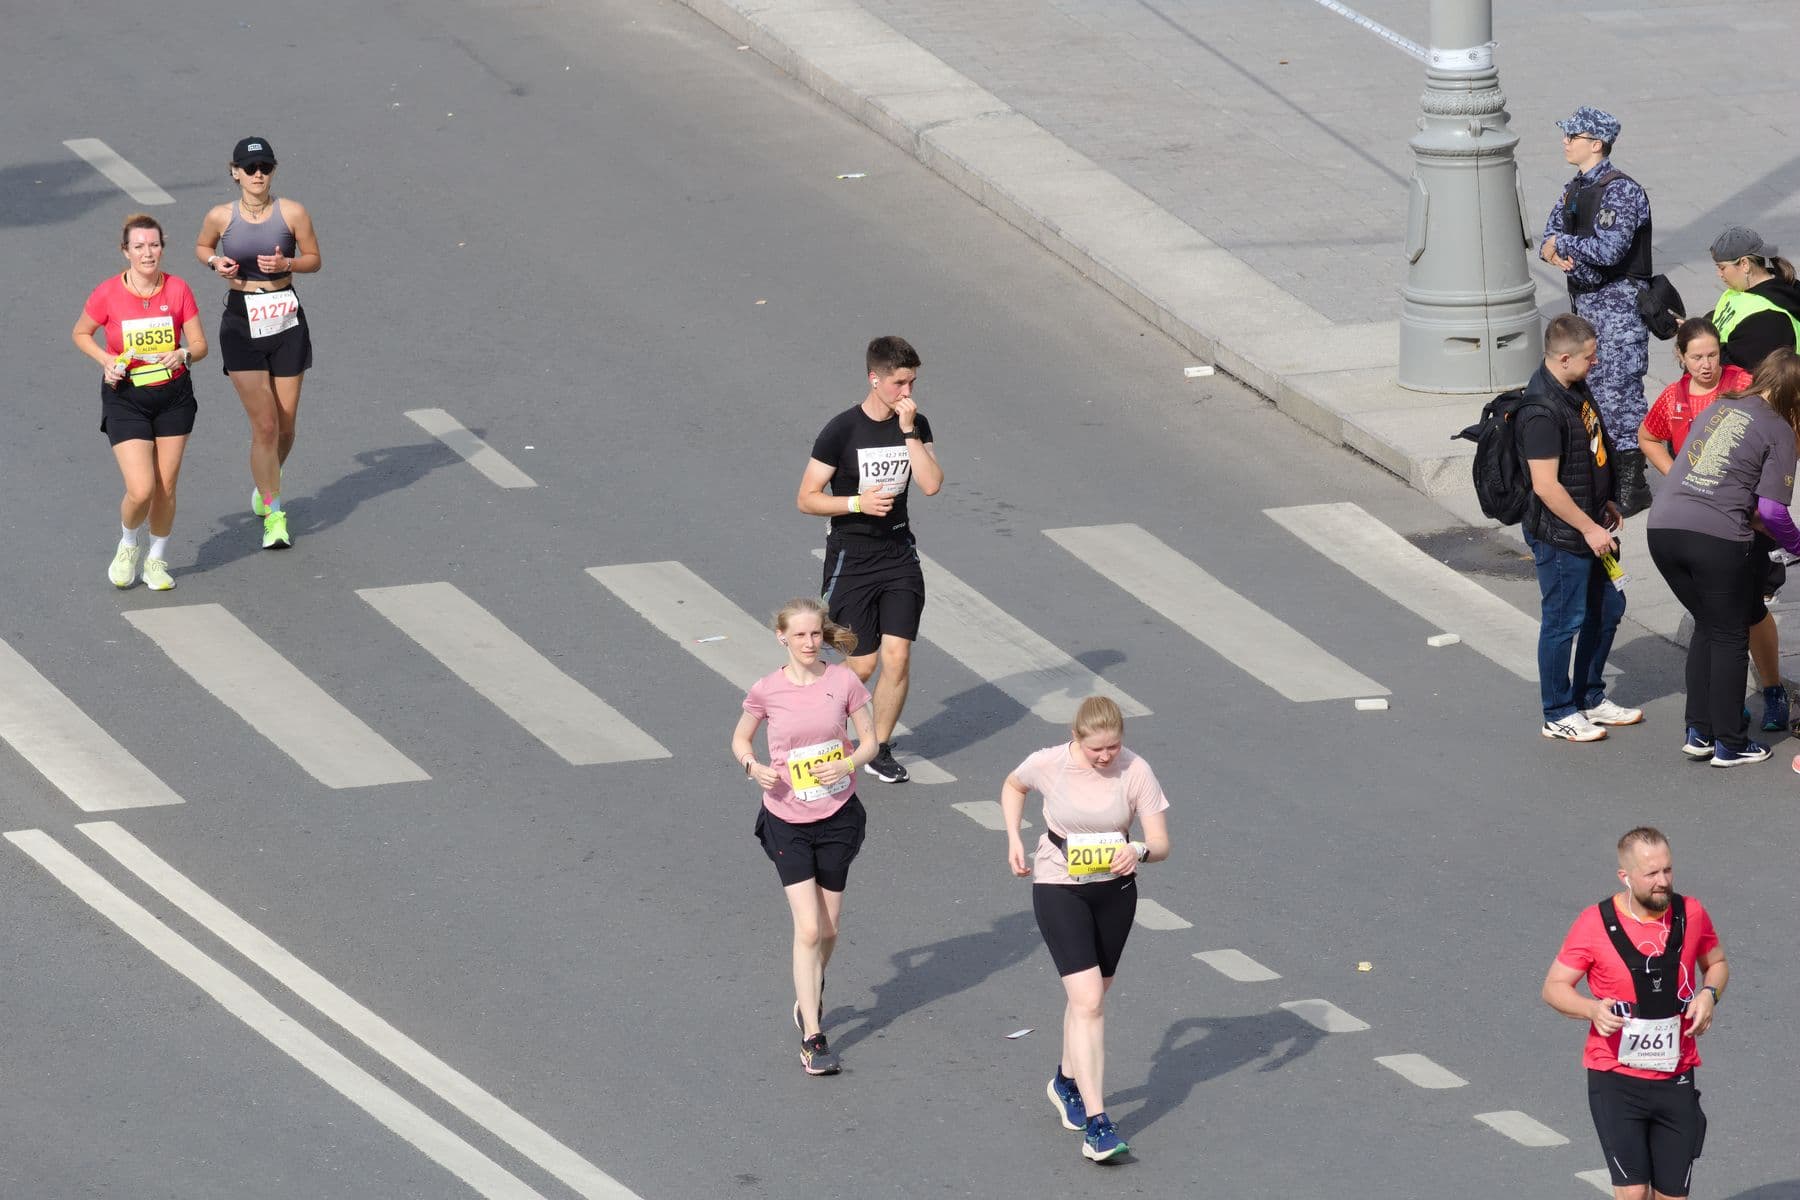
Footage of the actions, environments and edge cases your model must handle.
Scripted and spontaneous speech across speakers, accents, languages and noise conditions.
Handwriting, forms, receipts and domain-specific text, from conversational data to documents.
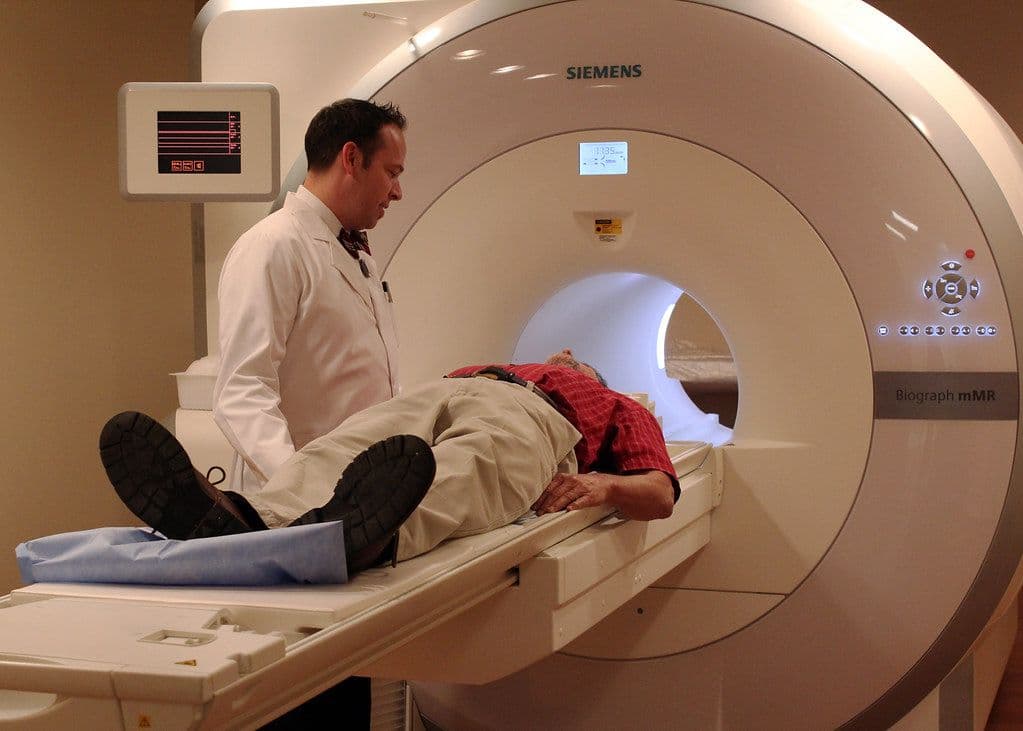
De-identified scans and clinical photos collected with consent and privacy safeguards.
Intraoral photos, impressions and radiographs collected with partner clinics.
Production-line, inspection and robot-cell imagery across shifts, products and defect types.
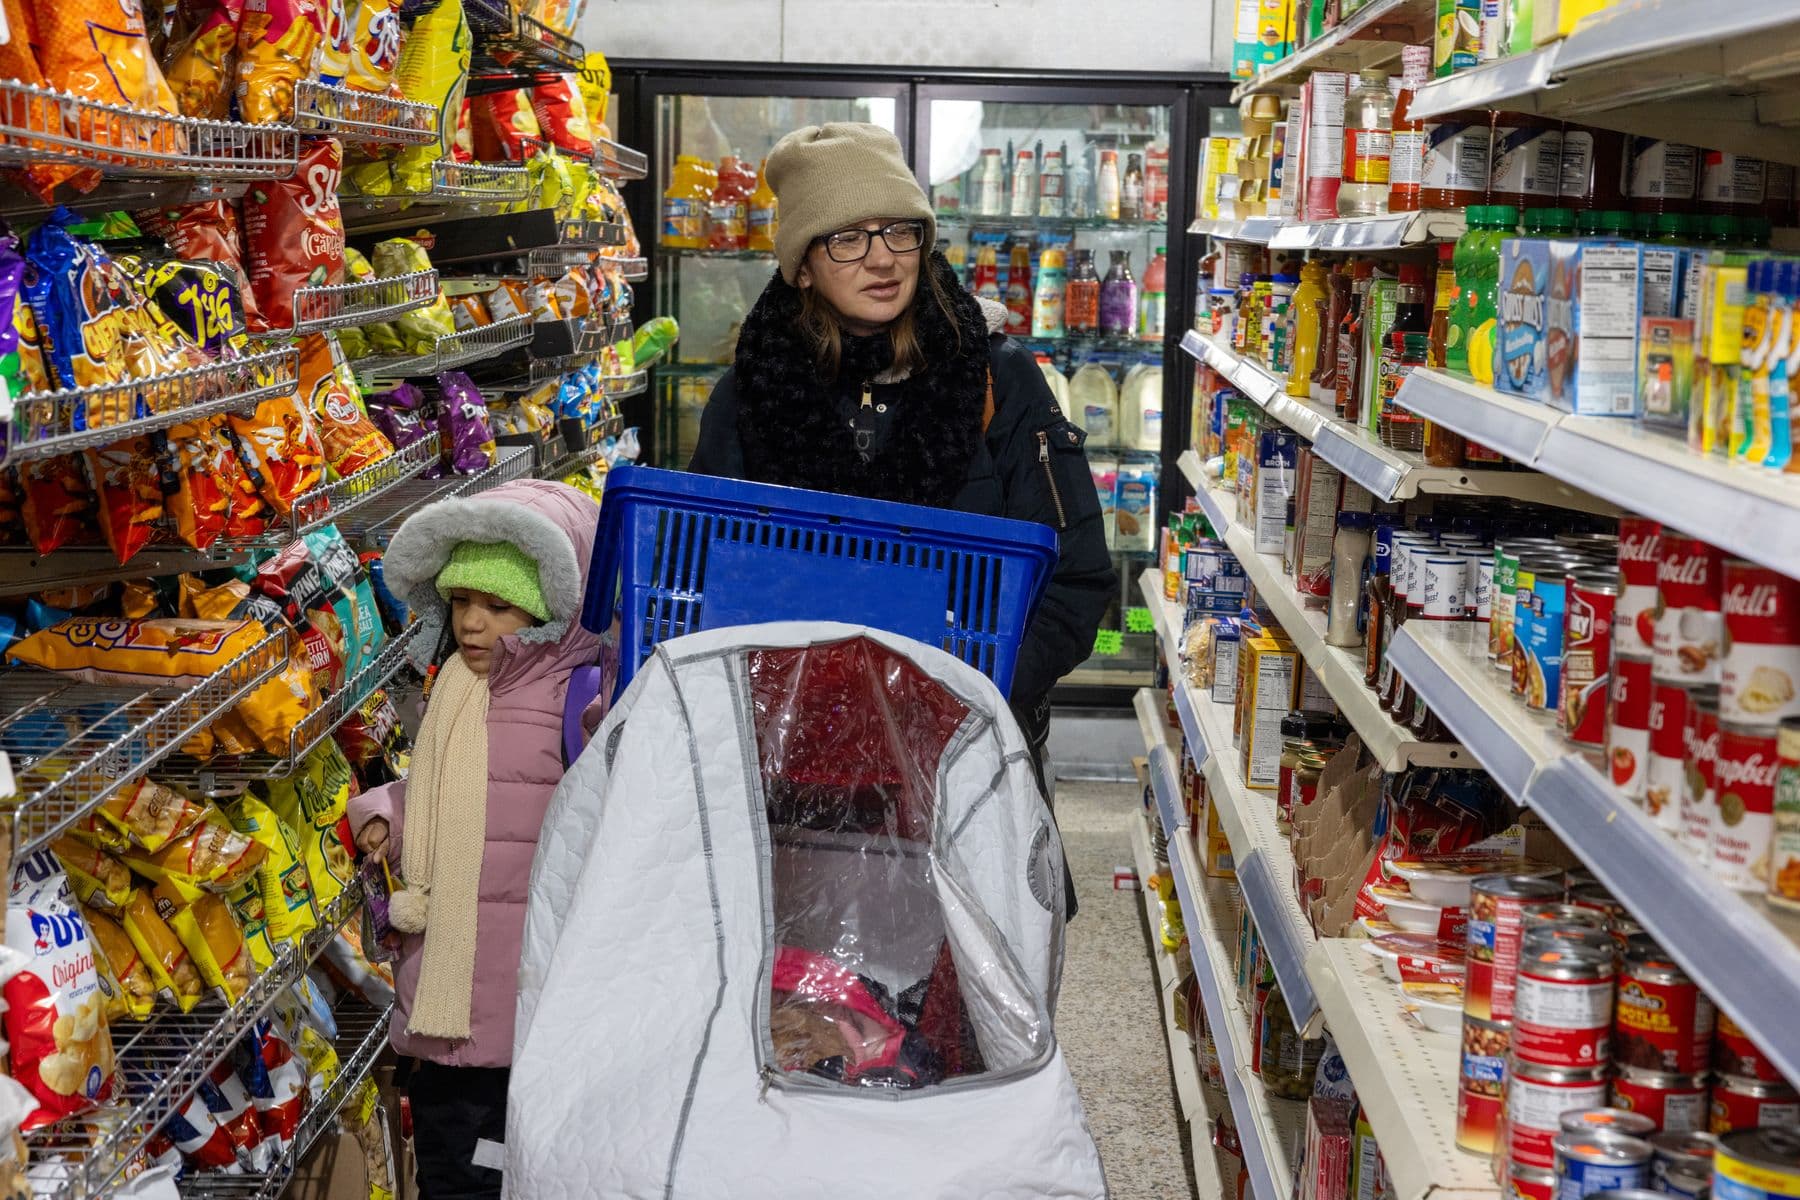
Shelves, products and store scenes across chains, layouts and lighting.
Field, crop and livestock imagery across seasons, growth stages and weather.
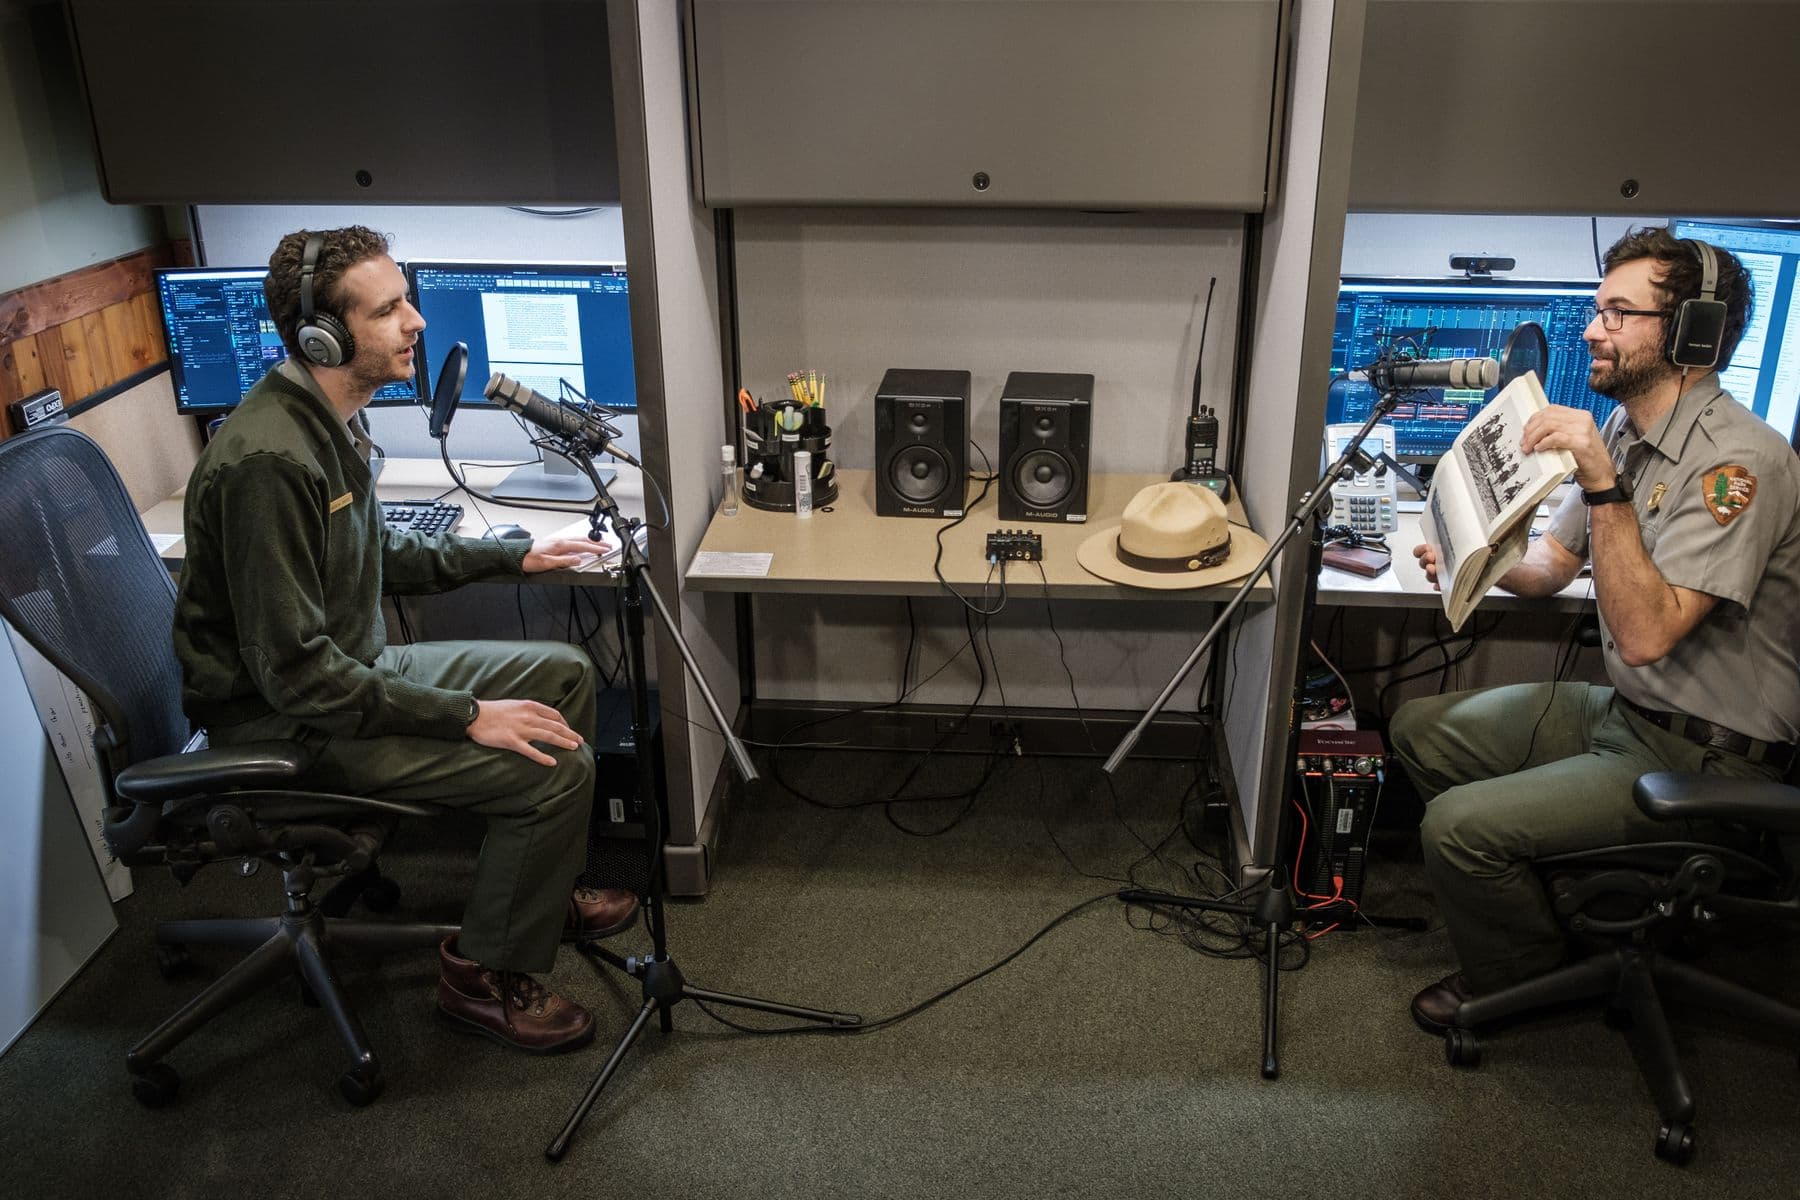
Multi-speaker dialogues and chats on the topics and in the languages you need.
Coverage tracking
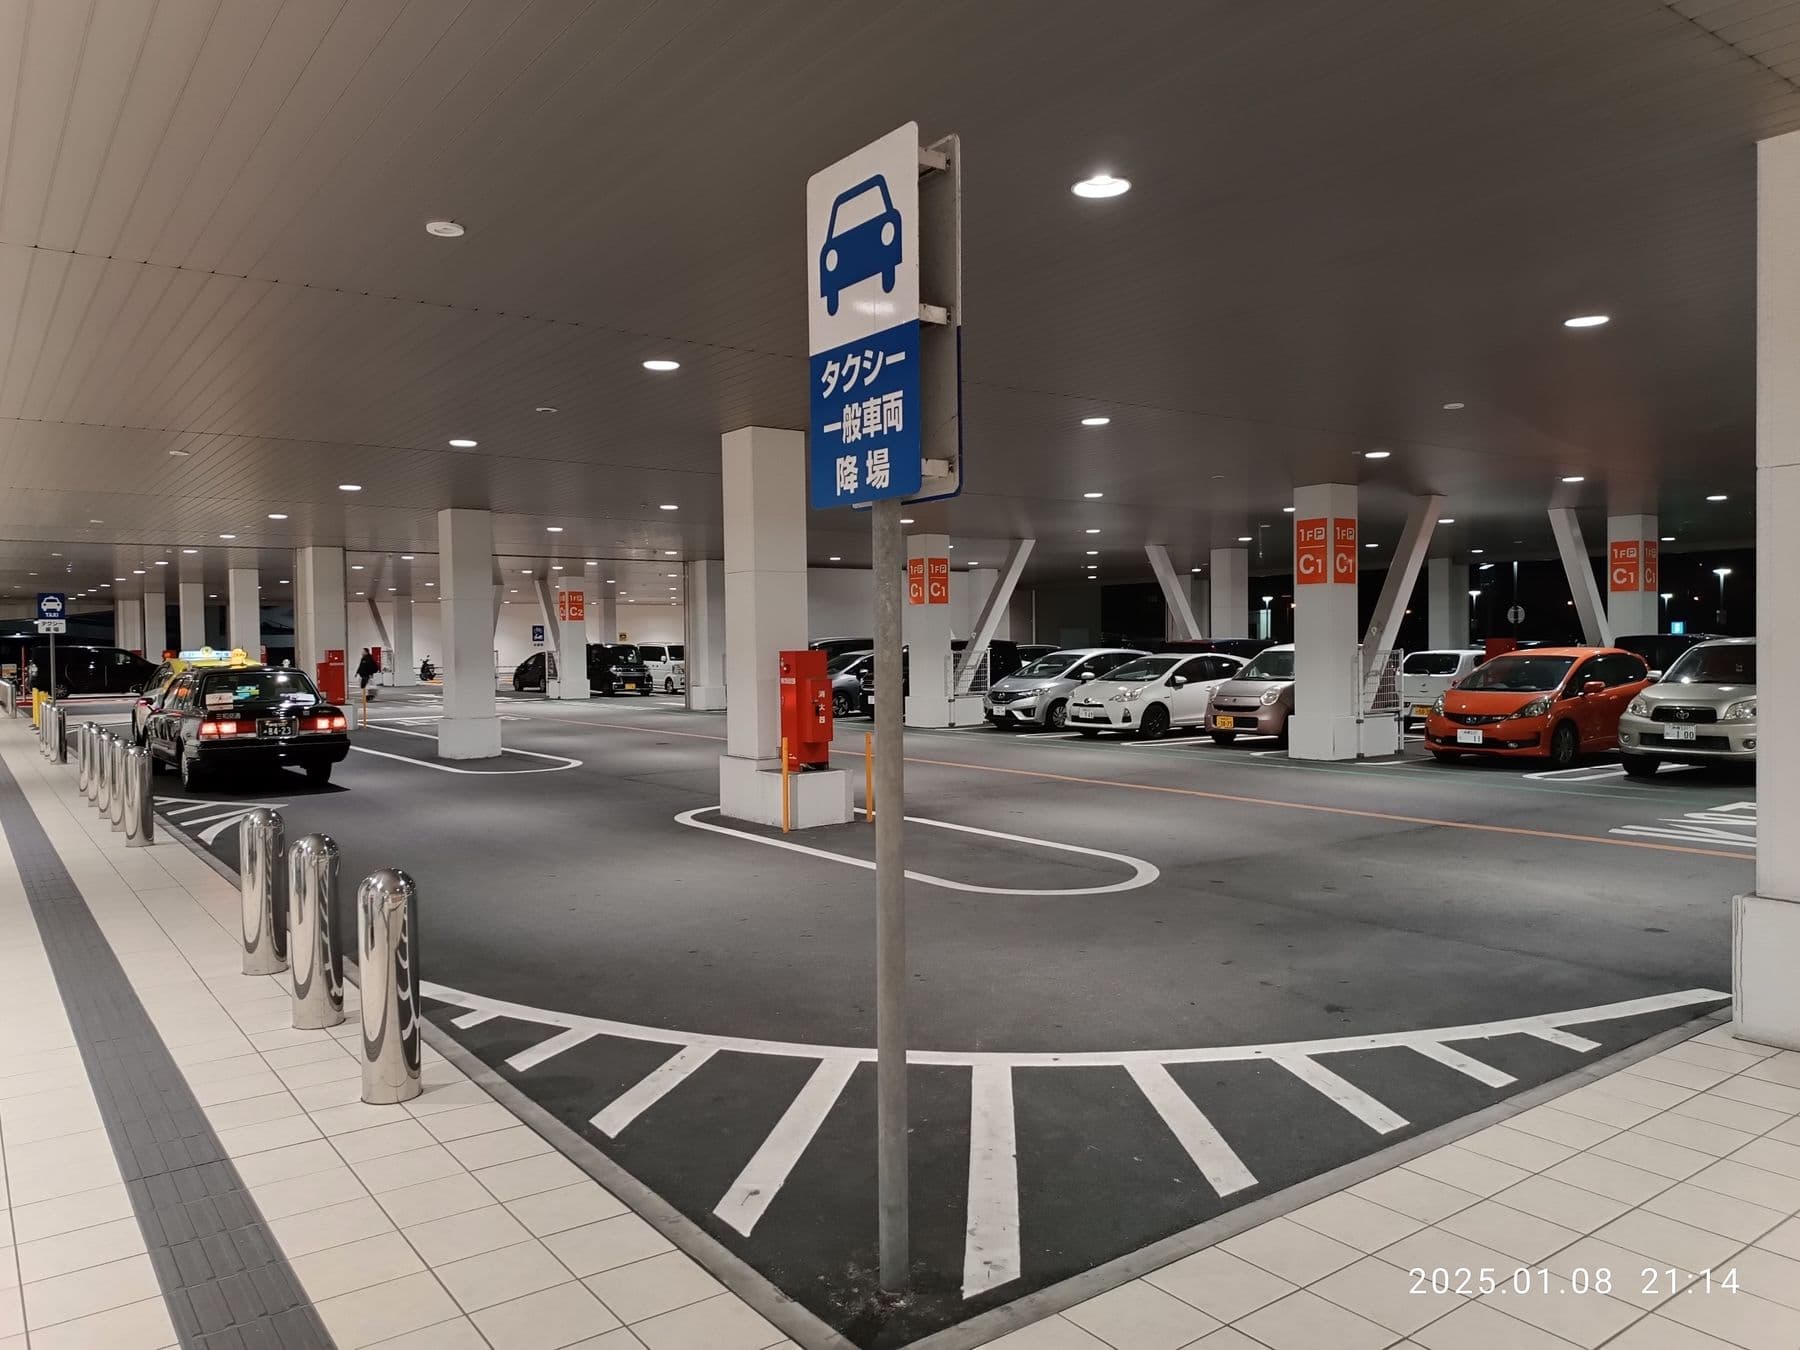
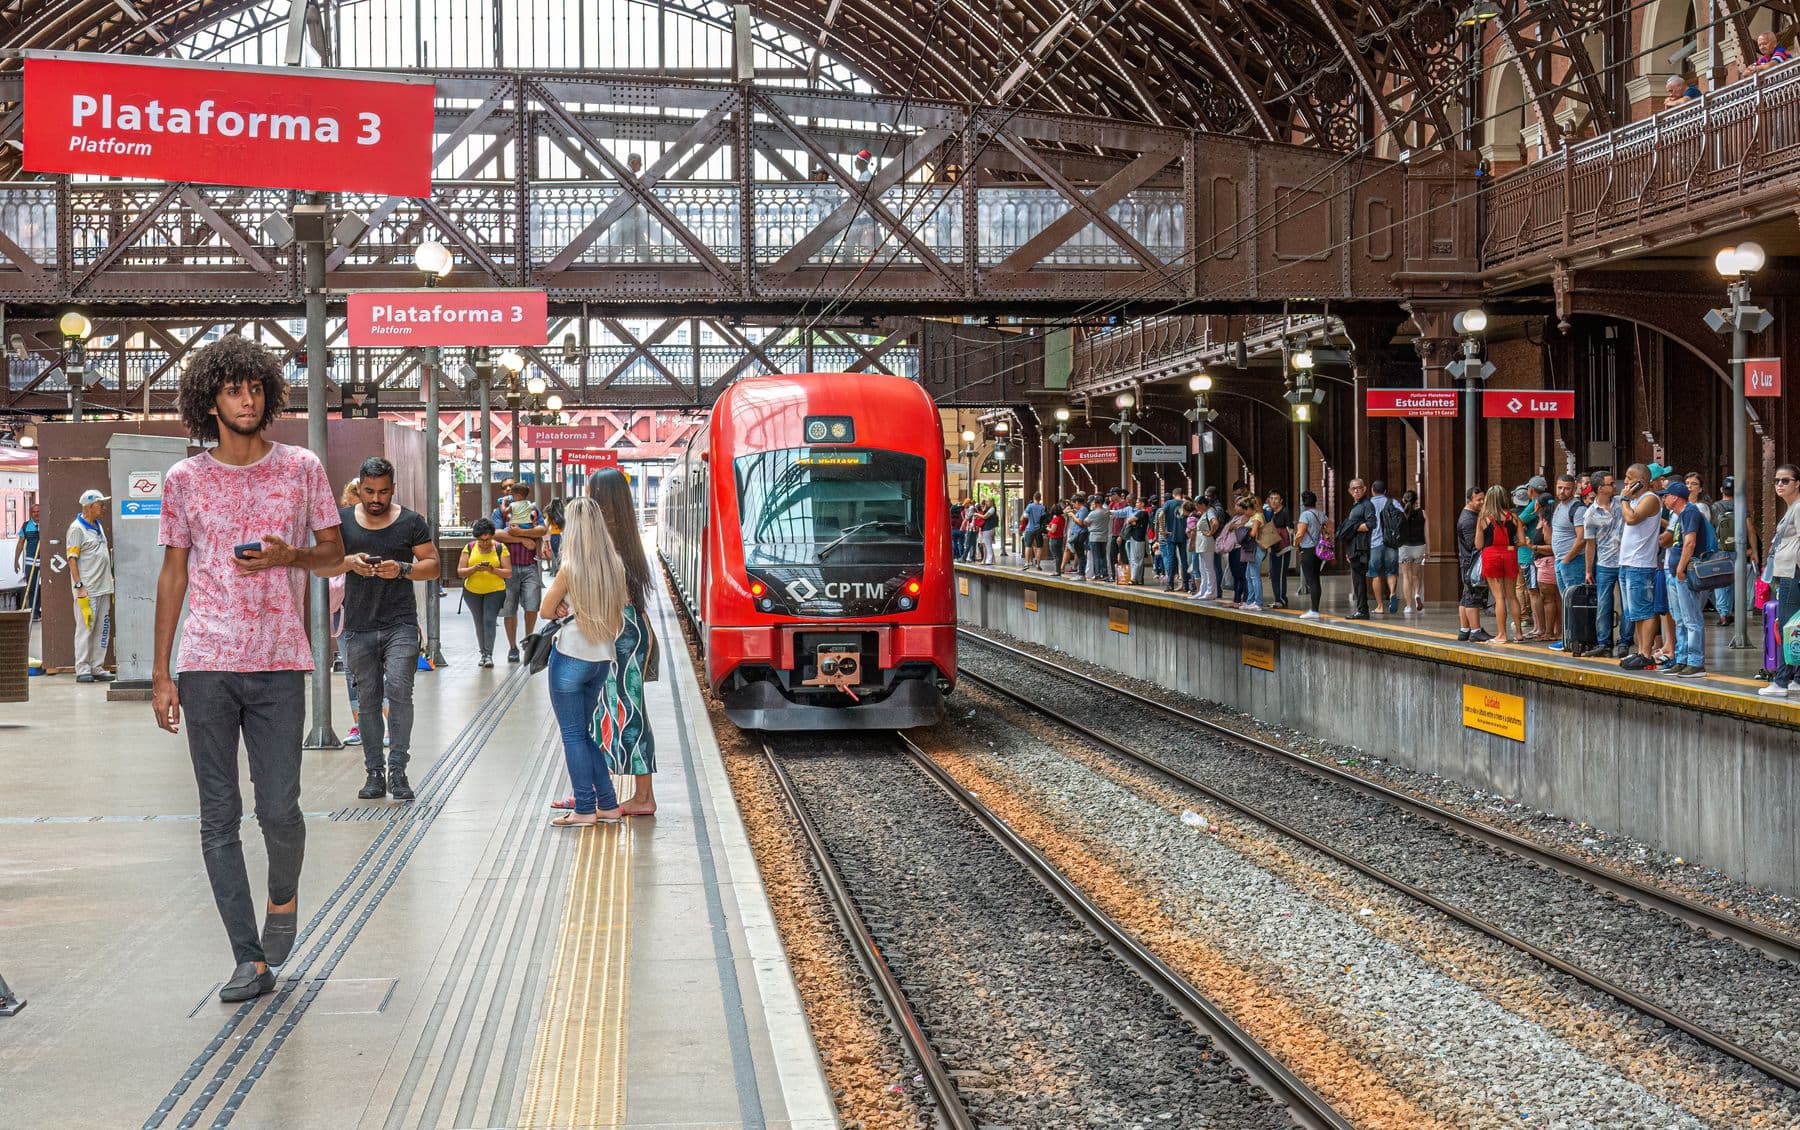
We plan collection around the scenes, conditions and devices your model will actually see, then track coverage until every cell of the brief is filled.
Coverage vs. collection brief · illustrative
urban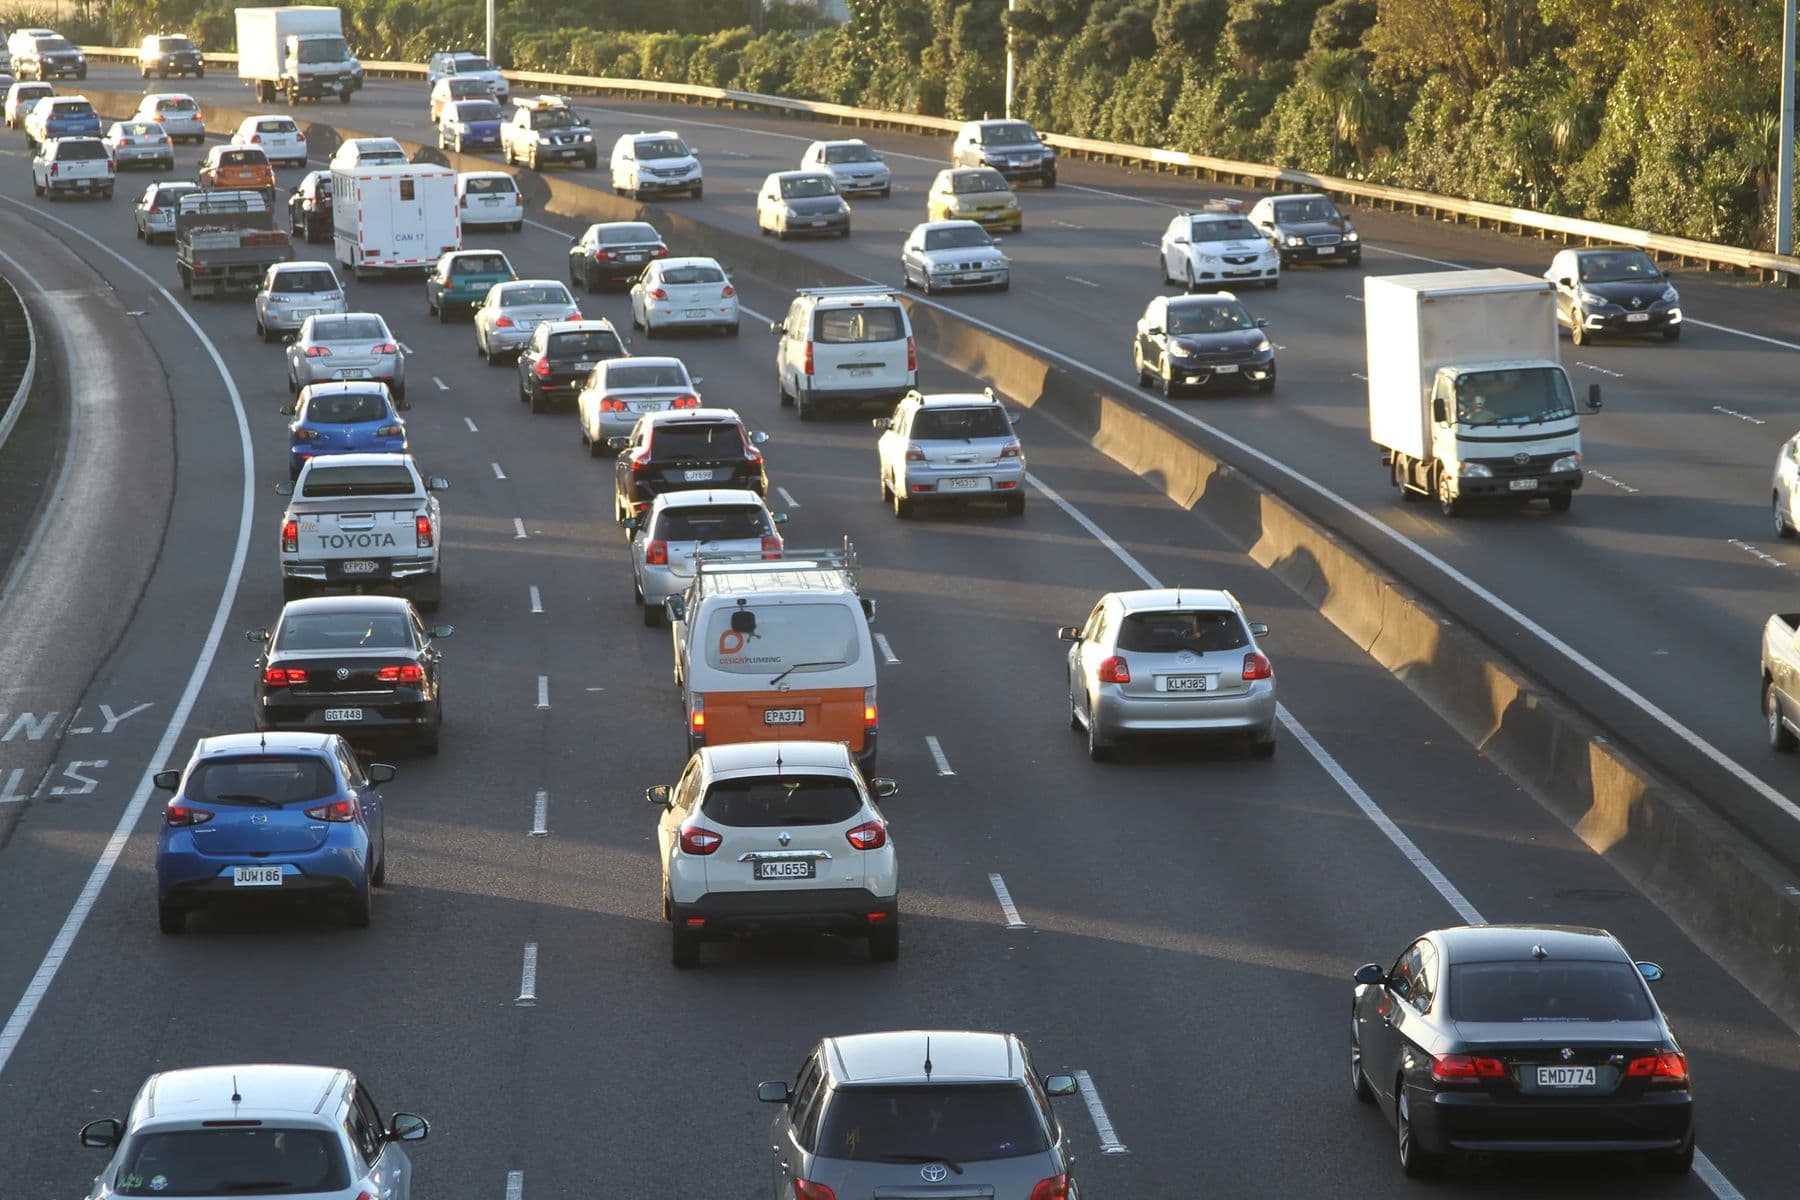 highway
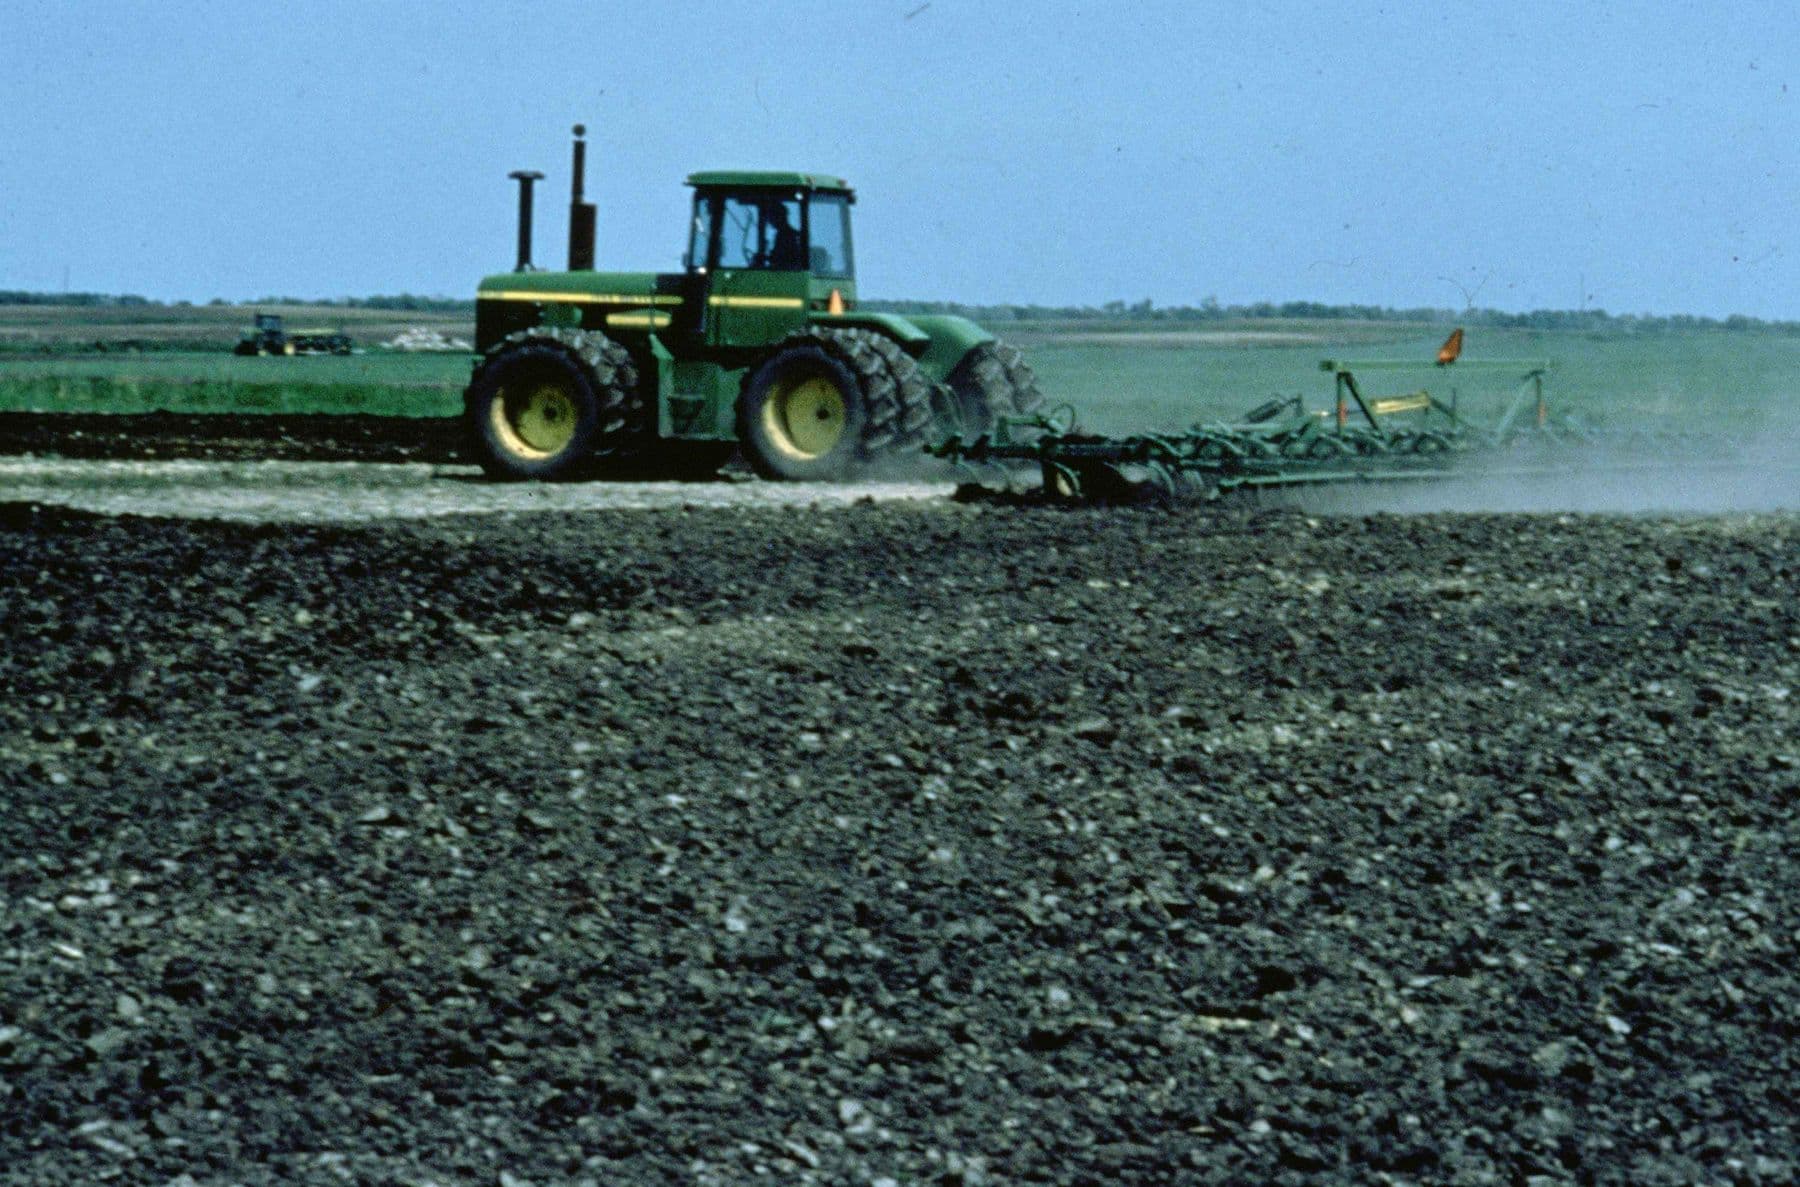 rural
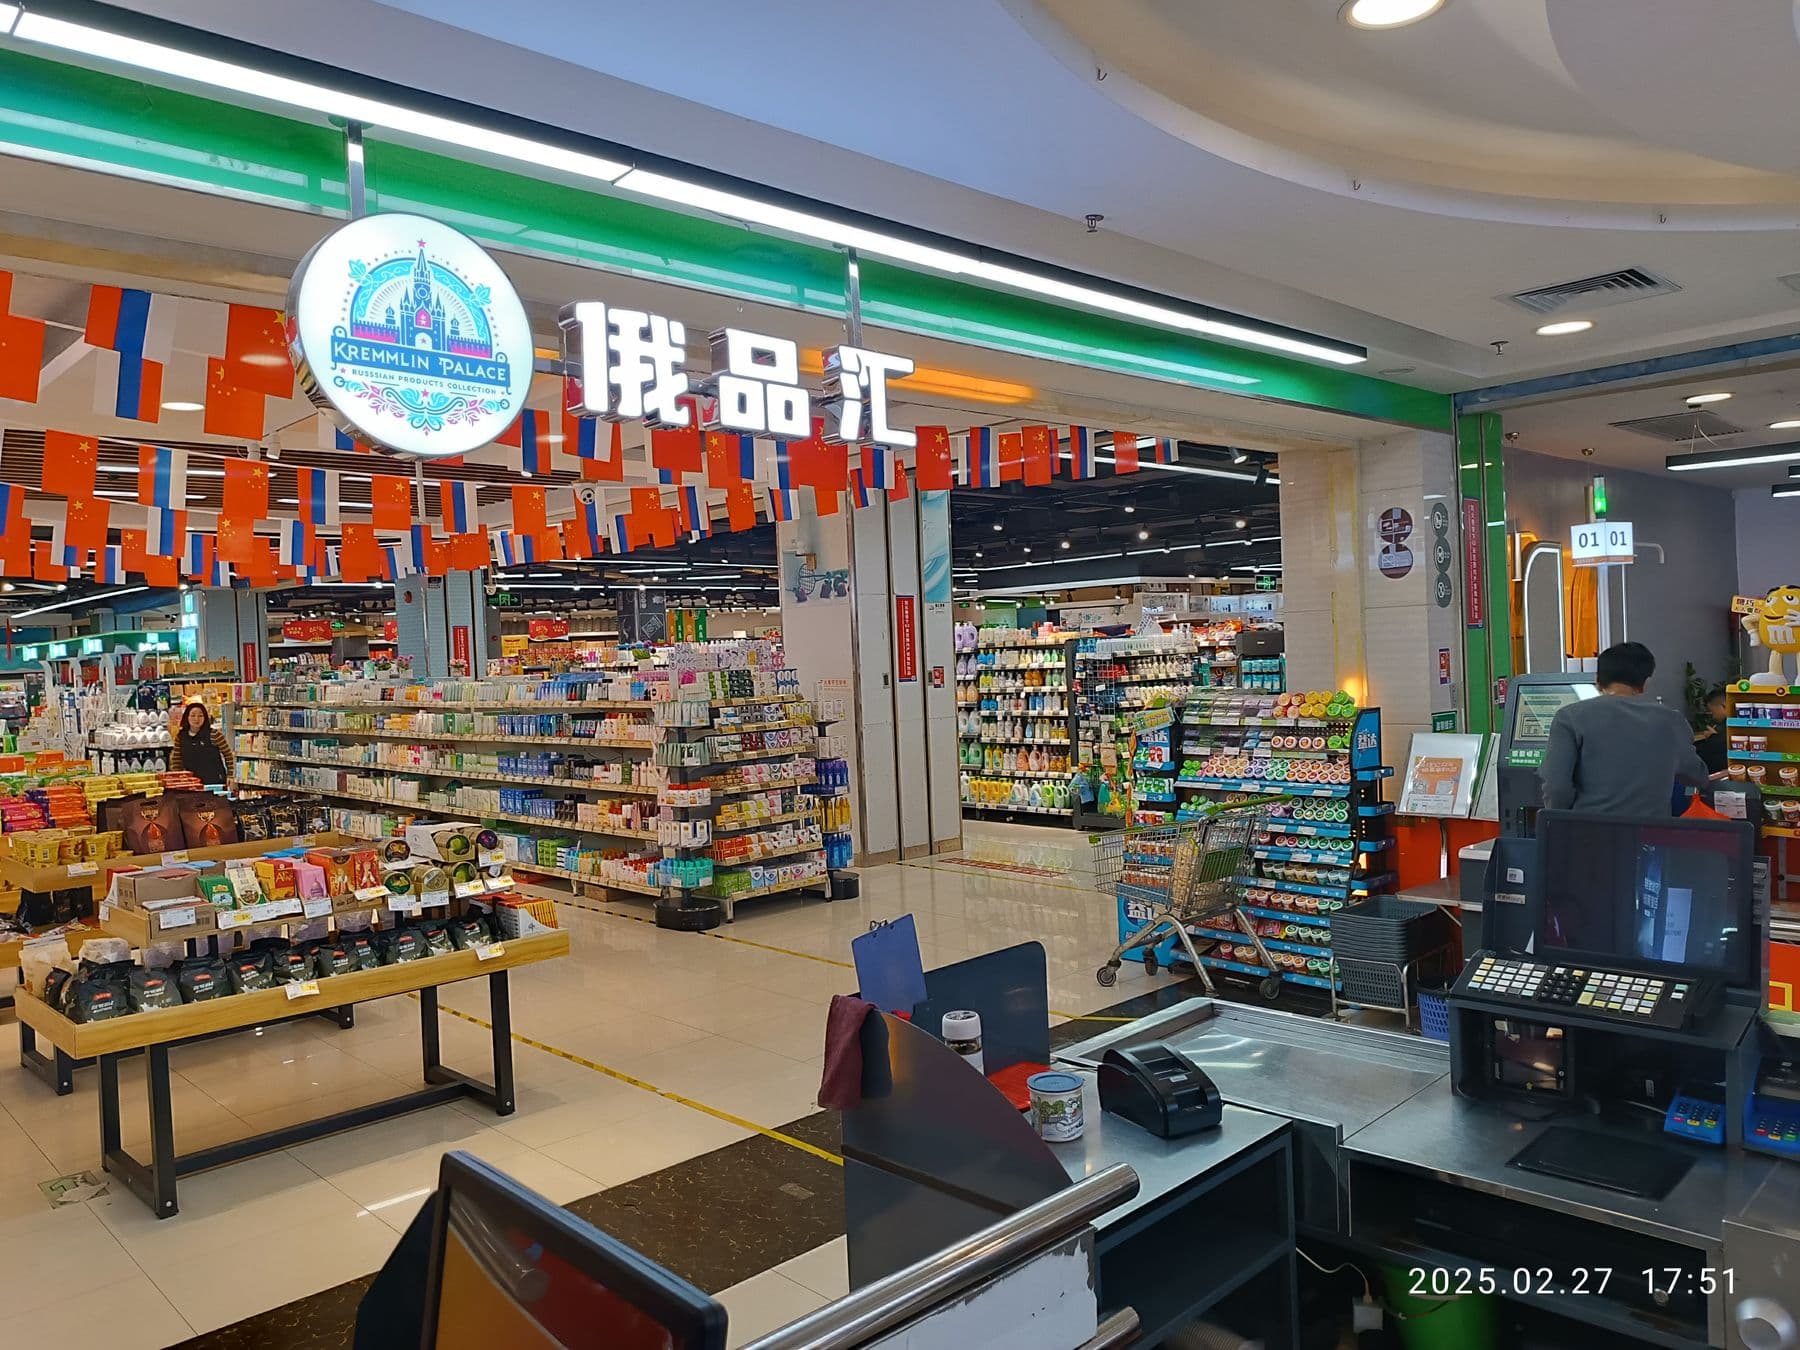 retail
 night
 transit
Use cases
Night, rain, rare objects and unusual angles your current dataset lacks.
Speech and text from new regions, accents and dialects.
Images of new SKUs or devices before real-world data exists.
Purpose-built, balanced test data for fair model evaluation.
How we work
We start with your data needs and target distribution, deploy the right collection methods, from controlled environments to real-world sourcing, and check quality at every stage. You get curated, structured data ready for your pipeline.
We review your data, edge cases and success criteria, then write annotation guidelines with you.
A trained team labels a pilot batch, following the agreed guidelines to the letter.
You review the pilot. We fold your feedback into the guidelines before scaling up.
Every batch passes peer review, expert QA and automated checks before it leaves us.
Labels ship in your format on your schedule, ready to drop into training.
Quality pipeline
Results
“For our ADAS project, Intellisane AI delivered precise vehicle annotations across diverse traffic scenes, including multiple object classes and occlusion scenarios. Their expertise in automotive data workflows and quality-first mindset helped us pass all validation checks, with timely delivery and professional communication throughout.”

Related
Supplying training data for autonomous vehicles, robotics, fintech, healthcare, voice assistants, legal AI and beyond.
FAQ
Something else on your mind? Email sales@intellisane.ai.
Get started
Tell us about your data. We'll come back with a plan and a free pilot batch so you can see the quality first.